Search 1M+ jobs Daily refreshed data
This repo lets you search 1M+ jobs, daily refreshed.
Riley-Dorrington/job-board-aggregator
Job board aggregator indexing 1,000,000+ active positions from 20,000+ companies across Greenhouse, Lever, Ashby, Workday, and other major ATS platforms. Multithreaded Python ETL pipeline, daily automated refreshes via GitHub Actions, filterable client-side search.
THE USEFUL PART
Job board aggregator indexing 1,000,000+ active positions from 20,000+ companies across Greenhouse, Lever, Ashby, Workday, and other major ATS platforms. Multithreaded Python ETL pipeline, daily automated refreshes via GitHub Actions, filterable client-side search.
THE STACKRADAR WALKTHROUGH
A short introduction from our reel. See the project README for the current details.
This repo lets you search 1M+ jobs, daily refreshed.
Beyond simple search, it offers advanced filters—by title, level, location, remote‐only, and even hide recruiter postings—so you see only the jobs that truly match you and export as CSV.
The built‐in heatmap visualizes job density by region, letting you target high‐opportunity areas and plan your applications with geographic insight to refine search.
GITHUB SNAPSHOT
Recorded counts, not a growth rate or a quality score.
OBSERVED STAR HISTORY
2 real daily observations. 187 → 187 stars.
FROM THE PROJECT
Source excerpts from the project's README. Not an independent review, verification or security audit.
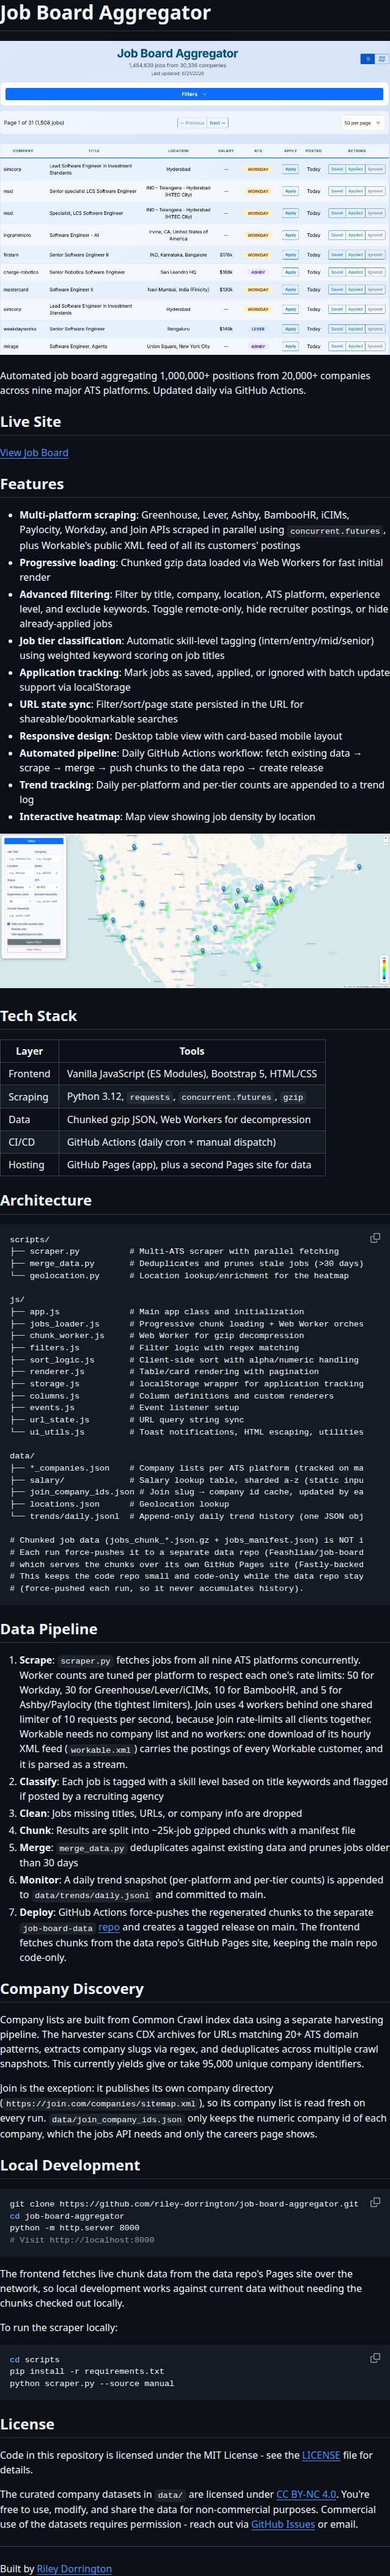
Automated job board aggregating 1,000,000+ positions from 20,000+ companies across nine major ATS platforms. Updated daily via GitHub Actions.
View Job Board
Multi-platform scraping: Greenhouse, Lever, Ashby, BambooHR, iCIMs, Paylocity, Workday, and Join APIs scraped in parallel using concurrent.futures, plus Workable's public XML feed of all its customers' postings
Progressive loading: Chunked gzip data loaded via Web Workers for fast initial render
Advanced filtering: Filter by title, company, location, ATS platform, experience level, and exclude keywords. Toggle remote-only, hide recruiter postings, or hide already-applied jobs
Job tier classification: Automatic skill-level tagging (intern/entry/mid/senior) using weighted keyword scoring on job titles
Application tracking: Mark jobs as saved, applied, or ignored with batch update support via localStorage
URL state sync: Filter/sort/page state persisted in the URL for shareable/bookmarkable searches
Responsive design: Desktop table view with card-based mobile layout
Automated pipeline: Daily GitHub Actions workflow: fetch existing data → scrape → merge → push chunks to the data repo → create release
Trend tracking: Daily per-platform and per-tier counts are appended to a trend log
Interactive heatmap: Map view showing job density by location
| Layer | Tools |
|---|---|
| Frontend | Vanilla JavaScript (ES Modules), Bootstrap 5, HTML/CSS |
| Scraping | Python 3.12, requests, concurrent.futures, gzip |
| Data | Chunked gzip JSON, Web Workers for decompression |
| CI/CD | GitHub Actions (daily cron + manual dispatch) |
| Hosting | GitHub Pages (app), plus a second Pages site for data |
scripts/
├── scraper.py          # Multi-ATS scraper with parallel fetching
├── merge_data.py       # Deduplicates and prunes stale jobs (>30 days)
└── geolocation.py      # Location lookup/enrichment for the heatmap

js/
├── app.js              # Main app class and initialization
├── jobs_loader.js      # Progressive chunk loading + Web Worker orchestration
├── chunk_worker.js     # Web Worker for gzip decompression
├── filters.js          # Filter logic with regex matching
├── sort_logic.js       # Client-side sort with alpha/numeric handling
├── renderer.js         # Table/card rendering with pagination
├── storage.js          # localStorage wrapper for application tracking
├── columns.js          # Column definitions and custom renderers
├── events.js           # Event listener setup
├── url_state.js        # URL query string sync
└── ui_utils.js         # Toast notifications, HTML escaping, utilities

data/
├── *_companies.json    # Company lists per ATS platform (tracked on main)
├── salary/             # Salary lookup table, sharded a-z (static input)
├── join_company_ids.json # Join slug → company id cache, updated by each run (tracked on main)
├── locations.json      # Geolocation lookup
└── trends/daily.jsonl  # Append-only daily trend history (one JSON object per line)

# Chunked job data (jobs_chunk_*.json.gz + jobs_manifest.json) is NOT in this repo.
# Each run force-pushes it to a separate data repo (Feashliaa/job-board-data),
# which serves the chunks over its own GitHub Pages site (Fastly-backed CDN).
# This keeps the code repo small and code-only while the data repo stays flat
# (force-pushed each run, so it never accumulates history).Scrape: scraper.py fetches jobs from all nine ATS platforms concurrently. Worker counts are tuned per platform to respect each one's rate limits: 50 for Workday, 30 for Greenhouse/Lever/iCIMs, 10 for BambooHR, and 5 for Ashby/Paylocity (the tightest limiters). Join uses 4 workers behind one shared limiter of 10 requests per second, because Join rate-limits all clients together. Workable needs no company list and no workers: one download of its hourly XML feed (workable.xml) carries the postings of every Workable customer, and it is parsed as a stream.
Classify: Each job is tagged with a skill level based on title keywords and flagged if posted by a recruiting agency
Clean: Jobs missing titles, URLs, or company info are dropped
Chunk: Results are split into ~25k-job gzipped chunks with a manifest file
Merge: merge_data.py deduplicates against existing data and prunes jobs older than 30 days
Monitor: A daily trend snapshot (per-platform and per-tier counts) is appended to data/trends/daily.jsonl and committed to main.
Deploy: GitHub Actions force-pushes the regenerated chunks to the separate job-board-data repo and creates a tagged release on main. The frontend fetches chunks from the data repo's GitHub Pages site, keeping the main repo code-only.
Company lists are built from Common Crawl index data using a separate harvesting pipeline. The harvester scans CDX archives for URLs matching 20+ ATS domain patterns, extracts company slugs via regex, and deduplicates across multiple crawl snapshots. This currently yields give or take 95,000 unique company identifiers.
Join is the exception: it publishes its own company directory (https://join.com/companies/sitemap.xml), so its company list is read fresh on every run. data/join_company_ids.json only keeps the numeric company id of each company, which the jobs API needs and only the careers page shows.
git clone https://github.com/riley-dorrington/job-board-aggregator.git
cd job-board-aggregator
python -m http.server 8000
# Visit http://localhost:8000
The frontend fetches live chunk data from the data repo's Pages site over the network, so local development works against current data without needing the chunks checked out locally.
To run the scraper locally:
cd scripts
pip install -r requirements.txt
python scraper.py --source manualCode in this repository is licensed under the MIT License - see the LICENSE file for details.
The curated company datasets in data/ are licensed under CC BY-NC 4.0. You're free to use, modify, and share the data for non-commercial purposes. Commercial use of the datasets requires permission - reach out via GitHub Issues or email.
Built by Riley Dorrington
Read the original READMEKEEP EXPLORING
 Repository preview
strelov1/freehire
Open-source search engine aggregating 3.3M+ tech jobs directly from 294k+ company career pages. Zero recruiters, no reposts.
git clone https://github.com/strelov1/freehire.gitzenhostai/9drive
Virtual storage gateway pooling multiple free Google Drive accounts into a combined 60GB+ high-speed personal bucket.
git clone https://github.com/zenhostai/9drive.git Repository screenshot
Tencent/libpag
The official rendering library for PAG (Portable Animated Graphics) files that renders After Effects animations natively across multiple platforms.
git clone https://github.com/Tencent/libpag.git
Short demos. New discoveries. Less noise in your feed.