FROM THE PROJECT
README & features
Source excerpts from the project's README. Not an independent review, verification or security audit.
Special thanks to:
Warp, built for coding with multiple AI agents
Available for MacOS, Linux, & Windows
CodeRabbit | AI Code Reviews
Cut code review time & bugs in half, instantly.
Pack your codebase into AI-friendly formats
Use Repomix online! 👉 repomix.com
Need discussion? Join us on Discord ! Share your experience and tips Stay updated on new features Get help with configuration and usage
[](https://www.npmjs.com/package/repomix) [](https://www.npmjs.com/package/repomix) [](https://github.com/yamadashy/repomix/actions?query=workflow%3A"ci") [](https://codecov.io/github/yamadashy/repomix) [](https://coderabbit.ai) [](https://github.com/sponsors/yamadashy) [](https://discord.gg/wNYzTwZFku)
[](https://deepwiki.com/yamadashy/repomix)
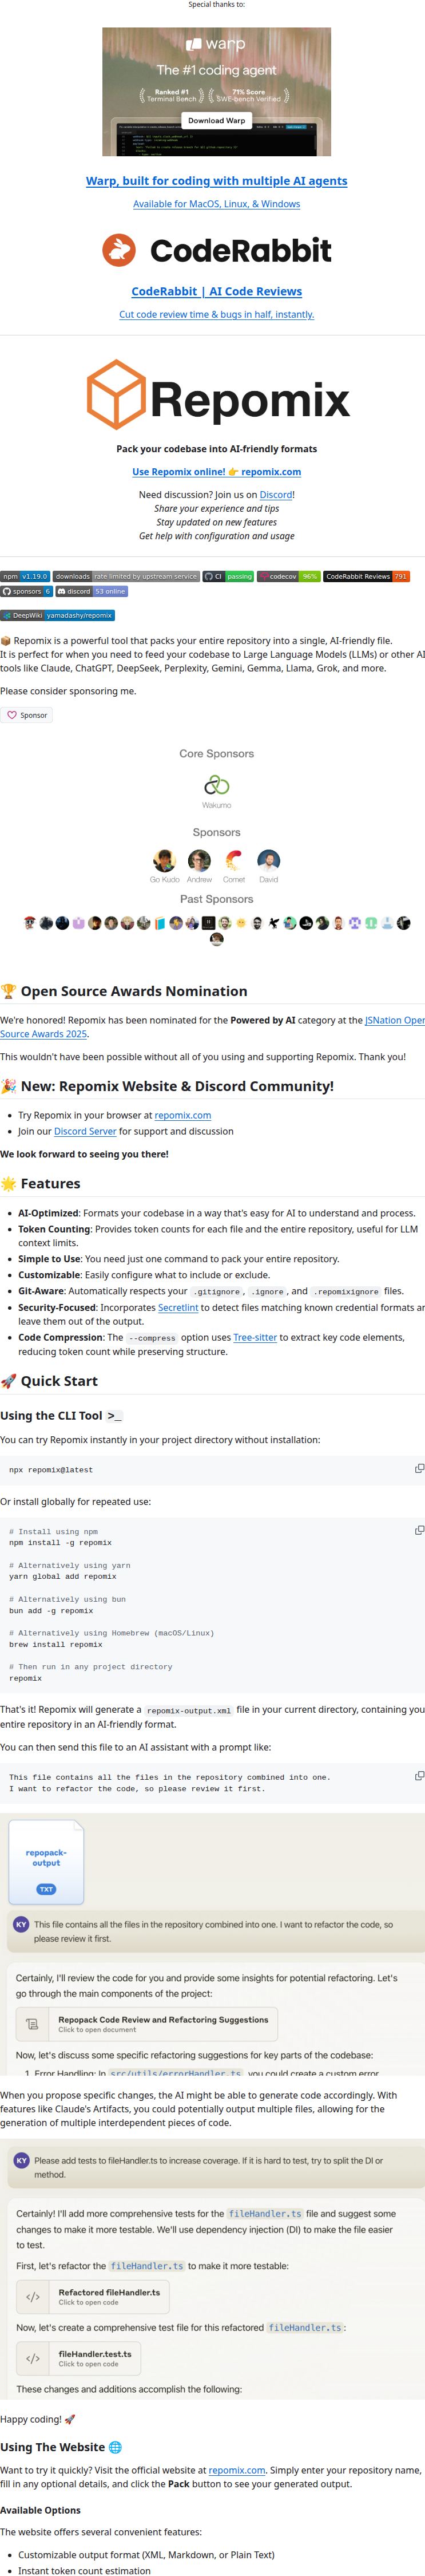
📦 Repomix is a powerful tool that packs your entire repository into a single, AI-friendly file. It is perfect for when you need to feed your codebase to Large Language Models (LLMs) or other AI tools like Claude, ChatGPT, DeepSeek, Perplexity, Gemini, Gemma, Llama, Grok, and more.
Please consider sponsoring me.
[](https://github.com/sponsors/yamadashy)
[](https://github.com/sponsors/yamadashy)
🏆 Open Source Awards Nomination
We're honored! Repomix has been nominated for the Powered by AI category at the JSNation Open Source Awards 2025.
This wouldn't have been possible without all of you using and supporting Repomix. Thank you!
🎉 New: Repomix Website & Discord Community!
Try Repomix in your browser at repomix.com
Join our Discord Server for support and discussion
We look forward to seeing you there!
🌟 Features
AI-Optimized: Formats your codebase in a way that's easy for AI to understand and process.
Token Counting: Provides token counts for each file and the entire repository, useful for LLM context limits.
Simple to Use: You need just one command to pack your entire repository.
Customizable: Easily configure what to include or exclude.
Git-Aware: Automatically respects your .gitignore, .ignore, and .repomixignore files.
Security-Focused: Incorporates Secretlint to detect files matching known credential formats and leave them out of the output.
Code Compression: The --compress option uses Tree-sitter to extract key code elements, reducing token count while preserving structure.
Using the CLI Tool >
You can try Repomix instantly in your project directory without installation:
npx repomix@latestOr install globally for repeated use:
# Install using npm
npm install -g repomix

# Alternatively using yarn
yarn global add repomix

# Alternatively using bun
bun add -g repomix

# Alternatively using Homebrew (macOS/Linux)
brew install repomix

# Then run in any project directory
repomix
That's it! Repomix will generate a repomix-output.xml file in your current directory, containing your entire repository in an AI-friendly format.
You can then send this file to an AI assistant with a prompt like:
This file contains all the files in the repository combined into one.
I want to refactor the code, so please review it first.
When you propose specific changes, the AI might be able to generate code accordingly. With features like Claude's Artifacts, you could potentially output multiple files, allowing for the generation of multiple interdependent pieces of code.
Happy coding! 🚀
Using The Website 🌐
Want to try it quickly? Visit the official website at repomix.com. Simply enter your repository name, fill in any optional details, and click the Pack button to see your generated output.
Available Options
The website offers several convenient features:
Customizable output format (XML, Markdown, or Plain Text)
Instant token count estimation
Much more!
Using The Browser Extension 🧩
Get instant access to Repomix directly from any GitHub repository! Our Chrome extension adds a convenient "Repomix" button to GitHub repository pages.
Install
Chrome Extension: Repomix - Chrome Web Store
Firefox Add-on: Repomix - Firefox Add-ons
Features
One-click access to Repomix for any GitHub repository
More exciting features coming soon!
Using The VSCode Extension ⚡️
A community-maintained VSCode extension called Repomix Runner (created by massdo) lets you run Repomix right inside your editor with just a few clicks. Run it on any folder, manage outputs seamlessly, and control everything through VSCode's intuitive interface.
Want your output as a file or just the content? Need automatic cleanup? This extension has you covered. Plus, it works smoothly with your existing repomix.config.json.
Try it now on the VSCode Marketplace! Source code is available on GitHub.
Alternative Tools 🛠️
If you're using Python, you might want to check out Gitingest, which is better suited for Python ecosystem and data science workflows: https://github.com/cyclotruc/gitingest
📊 Usage
To pack your entire repository:
repomixTo pack a specific directory:
repomix path/to/directoryTo pack specific files or directories using glob patterns:
repomix --include "src/**/*.ts,**/*.md"To exclude specific files or directories:
repomix --ignore "**/*.log,tmp/"To pack a remote repository:
repomix --remote https://github.com/yamadashy/repomix

# You can also use GitHub shorthand:
repomix --remote yamadashy/repomix

# You can specify the branch name, tag, or commit hash:
repomix --remote https://github.com/yamadashy/repomix --remote-branch main

# Or use a specific commit hash:
repomix --remote https://github.com/yamadashy/repomix --remote-branch 935b695

# Another convenient way is specifying the branch's URL
repomix --remote https://github.com/yamadashy/repomix/tree/main

# Commit's URL is also supported
repomix --remote https://github.com/yamadashy/repomix/commit/836abcd7335137228ad77feb28655d85712680f1
To pack files from a file list (pipe via stdin):
# Using find command
find src -name "*.ts" -type f | repomix --stdin

# Using git to get tracked files
git ls-files "*.ts" | repomix --stdin

# Using grep to find files containing specific content
grep -l "TODO" **/*.ts | repomix --stdin

# Using ripgrep to find files with specific content
rg -l "TODO|FIXME" --type ts | repomix --stdin

# Using ripgrep (rg) to find files
rg --files --type ts | repomix --stdin

# Using sharkdp/fd to find files
fd -e ts | repomix --stdin

# Using fzf to select from all files
fzf -m | repomix --stdin

# Interactive file selection with fzf
find . -name "*.ts" -type f | fzf -m | repomix --stdin

# Using ls with glob patterns
ls src/**/*.ts | repomix --stdin

# From a file containing file paths
cat file-list.txt | repomix --stdin

# Direct input with echo
echo -e "src/index.ts\nsrc/utils.ts" | repomix --stdin
The --stdin option allows you to pipe a list of file paths to Repomix, giving you ultimate flexibility in selecting which files to pack.
When using --stdin, the specified files are effectively added to the include patterns. This means that the normal include and ignore behavior still applies - files specified via stdin will still be excluded if they match ignore patterns.
When using --stdin, file paths can be relative or absolute, and Repomix will automatically handle path resolution and deduplication.
To include git logs in the output:
# Include git logs with default count (50 commits)
repomix --include-logs

# Include git logs with specific commit count
repomix --include-logs --include-logs-count 10

# Combine with diffs for comprehensive git context
repomix --include-logs --include-diffs
The git logs include commit dates, messages, and file paths for each commit, providing valuable context for AI analysis of code evolution and development patterns.
To compress the output:
repomix --compress

# You can also use it with remote repositories:
repomix --remote yamadashy/repomix --compress
To initialize a new configuration file (repomix.config.json):
repomix --initOnce you have generated the packed file, you can use it with Generative AI tools like ChatGPT, DeepSeek, Perplexity, Gemini, Gemma, Llama, Grok, and more.
Docker Usage 🐳
You can also run Repomix using Docker. This is useful if you want to run Repomix in an isolated environment or prefer using containers.
Basic usage (current directory):
docker run -v .:/app -it --rm ghcr.io/yamadashy/repomixTo pack a specific directory:
docker run -v .:/app -it --rm ghcr.io/yamadashy/repomix path/to/directoryProcess a remote repository and output to a output directory:
docker run -v ./output:/app -it --rm ghcr.io/yamadashy/repomix --remote https://github.com/yamadashy/repomixPrompt Examples
Once you have generated the packed file with Repomix, you can use it with AI tools like ChatGPT, DeepSeek, Perplexity, Gemini, Gemma, Llama, Grok, and more. Here are some example prompts to get you started:
Code Review and Refactoring
For a comprehensive code review and refactoring suggestions:
This file contains my entire codebase. Please review the overall structure and suggest any improvements or refactoring opportunities, focusing on maintainability and scalability.Documentation Generation
To generate project documentation:
Based on the codebase in this file, please generate a detailed README.md that includes an overview of the project, its main features, setup instructions, and usage examples.Test Case Generation
For generating test cases:
Analyze the code in this file and suggest a comprehensive set of unit tests for the main functions and classes. Include edge cases and potential error scenarios.Code Quality Assessment
Evaluate code quality and adherence to best practices:
Review the codebase for adherence to coding best practices and industry standards. Identify areas where the code could be improved in terms of readability, maintainability, and efficiency. Suggest specific changes to align the code with best practices.Library Overview
Get a high-level understanding of the library
This file contains the entire codebase of library. Please provide a comprehensive overview of the library, including its main purpose, key features, and overall architecture.Feel free to modify these prompts based on your specific needs and the capabilities of the AI tool you're using.
Community Discussion
Check out our community discussion where users share:
Which AI tools they're using with Repomix
Effective prompts they've discovered
How Repomix has helped them
Tips and tricks for getting the most out of AI code analysis
Feel free to join the discussion and share your own experiences! Your insights could help others make better use of Repomix.
Output File Format
Repomix generates a single file with clear separators between different parts of your codebase. To enhance AI comprehension, the output file begins with an AI-oriented explanation, making it easier for AI models to understand the context and structure of the packed repository.
XML Format (default)
The XML format structures the content in a hierarchical manner:
This file is a merged representation of the entire codebase, combining all repository files into a single document.

<file_summary>
  (Metadata and usage AI instructions)
</file_summary>

<directory_structure>
src/
cli/
cliOutput.ts
index.ts

(...remaining directories)
</directory_structure>

<files>
<file path="src/index.js">
  // File contents here
</file>

(...remaining files)
</files>

<instruction>
(Custom instructions from `output.instructionFilePath`)
</instruction>
For those interested in the potential of XML tags in AI contexts: https://docs.anthropic.com/en/docs/build-with-claude/prompt-engineering/use-xml-tags
When your prompts involve multiple components like context, instructions, and examples, XML tags can be a game-changer. They help Claude parse your prompts more accurately, leading to higher-quality outputs.
This means that the XML output from Repomix is not just a different format, but potentially a more effective way to feed your codebase into AI systems for analysis, code review, or other tasks.
Markdown Format
To generate output in Markdown format, use the --style markdown option:
repomix --style markdownThe Markdown format structures the content in a hierarchical manner:
This file is a merged representation of the entire codebase, combining all repository files into a single document.

# File Summary

(Metadata and usage AI instructions)

# Repository Structure
src/ cli/ cliOutput.ts index.ts
(...remaining directories)

# Repository Files

## File: src/index.js
// File contents here
(...remaining files)

# Instruction

(Custom instructions from `output.instructionFilePath`)
This format provides a clean, readable structure that is both human-friendly and easily parseable by AI systems.
JSON Format
To generate output in JSON format, use the --style json option:
repomix --style jsonThe JSON format structures the content as a hierarchical JSON object with camelCase property names:
{
  "fileSummary": {
    "generationHeader": "This file is a merged representation of the entire codebase, combined into a single document by Repomix.",
    "purpose": "This file contains a packed representation of the entire repository's contents...",
    "fileFormat": "The content is organized as follows...",
    "usageGuidelines": "- This file should be treated as read-only...",
    "notes": "- Some files may have been excluded based on .gitignore, .ignore, and .repomixignore rules..."
  },
  "userProvidedHeader": "Custom header text if specified",
  "directoryStructure": "src/\n  cli/\n    cliOutput.ts\n    index.ts\n  config/\n    configLoader.ts",
  "files": {
    "src/index.js": "// File contents here",
    "src/utils.js": "// File contents here"
  },
  "instruction": "Custom instructions from instructionFilePath"
}
This format is ideal for:
Programmatic processing: Easy to parse and manipulate with JSON libraries
API integration: Direct consumption by web services and applications
AI tool compatibility: Structured format for machine learning and AI systems
Data analysis: Straightforward extraction of specific information using tools like jq
Working with JSON Output Using jq
The JSON format makes it easy to extract specific information programmatically:
# List all file paths
cat repomix-output.json | jq -r '.files | keys[]'

# Count total number of files
cat repomix-output.json | jq '.files | keys | length'

# Extract specific file content
cat repomix-output.json | jq -r '.files["README.md"]'
cat repomix-output.json | jq -r '.files["src/index.js"]'

# Find files by extension
cat repomix-output.json | jq -r '.files | keys[] | select(endswith(".ts"))'

# Get files containing specific text
cat repomix-output.json | jq -r '.files | to_entries[] | select(.value | contains("function")) | .key'

# Extract directory structure
cat repomix-output.json | jq -r '.directoryStructure'

# Get file summary information
cat repomix-output.json | jq '.fileSummary.purpose'
cat repomix-output.json | jq -r '.fileSummary.generationHeader'

# Extract user-provided header (if exists)
cat repomix-output.json | jq -r '.userProvidedHeader // "No header provided"'

# Create a file list with sizes
cat repomix-output.json | jq -r '.files | to_entries[] | "\(.key): \(.value | length) characters"'
Plain Text Format
To generate output in plain text format, use the --style plain option:
repomix --style plainThis file is a merged representation of the entire codebase, combining all repository files into a single document.
================================================================
File Summary
================================================================
(Metadata and usage AI instructions)
================================================================
Directory Structure
================================================================
src/
cli/
cliOutput.ts
index.ts
config/
configLoader.ts
(...remaining directories)
================================================================
Files
================================================================
================
File: src/index.js
================
// File contents here
================
File: src/utils.js
================
// File contents here
(...remaining files)
================================================================
Instruction
================================================================
(Custom instructions from `output.instructionFilePath`)Basic Options
-v, --version: Show version information and exit
CLI Input/Output Options
| Option | Description |
|---|---|
| --verbose | Enable detailed debug logging (shows file processing, token counts, and configuration details) |
| --quiet | Suppress all console output except errors (useful for scripting) |
| --stdout | Write packed output directly to stdout instead of a file (suppresses all logging) |
| --stdin | Read file paths from stdin, one per line (specified files are processed directly) |
| --copy | Copy the generated output to system clipboard after processing |
| --token-count-tree [threshold] | Show file tree with token counts; optional threshold to show only files with ≥N tokens (e.g., --token-count-tree 100) |
| --top-files-len | Number of largest files to show in summary (default: 5) |
Repomix Output Options
| Option | Description |
|---|---|
| -o, --output | Output file path (default: repomix-output.xml, use "-" for stdout) |
| --style | Output format: xml, markdown, json, or plain (default: xml) |
| --output-file-path-style | How file paths are shown in output: target-relative or cwd-relative (default: target-relative) |
| --parsable-style | Escape special characters to ensure valid XML/Markdown (needed when output contains code that breaks formatting) |
| --compress | Extract essential code structure (classes, functions, interfaces) using Tree-sitter parsing |
| --output-show-line-numbers | Prefix each line with its line number in the output |
| --no-file-summary | Omit the file summary section from output |
| --no-directory-structure | Omit the directory tree visualization from output |
| --no-files | Generate metadata only without file contents (useful for repository analysis) |
| --remove-comments | Strip all code comments before packing |
| --remove-empty-lines | Remove blank lines from all files |
| --truncate-base64 | Truncate long base64 data strings to reduce output size |
| --header-text | Custom text to include at the beginning of the output |
| --instruction-file-path | Path to file containing custom instructions to include in output |
| --split-output | Split output into multiple numbered files (e.g., repomix-output.1.xml); size like 500kb, 2mb, or 1.5mb |
| --include-empty-directories | Include folders with no files in directory structure |
| --include-full-directory-structure | Show complete directory tree in output, including files not matched by --include patterns |
| --no-git-sort-by-changes | Don't sort files by git change frequency (default: most changed files first) |
| --include-diffs | Add git diff section showing working tree and staged changes |
| --include-logs | Add git commit history with messages and changed files |
| --include-logs-count | Number of recent commits to include with --include-logs (default: 50) |
File Selection Options
| Option | Description |
|---|---|
| --include | Include only files matching these glob patterns (comma-separated, e.g., "src//.js,.md") |
| -i, --ignore | Additional patterns to exclude (comma-separated, e.g., ".test.js,docs/") |
| --no-gitignore | Don't use .gitignore rules for filtering files |
| --no-dot-ignore | Don't use .ignore rules for filtering files |
| --no-default-patterns | Don't apply built-in ignore patterns (node_modules, .git, build dirs, etc.) |
Remote Repository Options
| Option | Description |
|---|---|
| --remote | Clone and pack a remote repository (GitHub URL or user/repo format) |
| --remote-branch | Specific branch, tag, or commit to use (default: repository's default branch) |
| --remote-trust-config | Trust and load config files from remote repositories (disabled by default for security). On an interactive terminal, the config is shown and you are asked to confirm |
Configuration Options
| Option | Description |
|---|---|
| -c, --config | Use custom config file instead of repomix.config.json |
| --init | Create a new repomix.config.json file with defaults |
| --global | With --init, create config in home directory instead of current directory |
Security Options
--no-security-check: Skip scanning for sensitive data like API keys and passwords
Token Count Options
--token-count-encoding : Tokenizer model for counting: o200k_base (GPT-4o), cl100k_base (GPT-3.5/4), etc. (default: o200k_base)
--token-budget : Fail with a non-zero exit code when the packed output exceeds N tokens. Useful as a guard in CI pipelines and agent workflows to keep output within a target model's context window. The output is still generated; only the exit code signals the overflow.
MCP
--mcp: Run as Model Context Protocol server for AI tool integration
--sandbox [dir]: (with --mcp) confine the MCP server's file tools to a workspace directory (defaults to the working directory; e.g. --sandbox path/to/project) — every path is relative to that root, absolute/host paths are refused, and remote packing, skill generation, and attaching external outputs are disabled.
Agent Skills Generation
| Option | Description |
|---|---|
| --skill-generate [name] | Generate Claude Agent Skills format output to .claude/skills/ / directory (name auto-generated if omitted) |
| --skill-project-name | Override the project name used in generated Skills descriptions |
| --skill-output | Specify skill output directory path directly (skips location prompt) |
| -f, --force | Skip all confirmation prompts (skill directory overwrite, remote config trust) |
Watch Mode
-w, --watch: Watch for file changes and automatically re-pack. Debounces rapid changes (300ms) and logs a timestamp on each rebuild. Stop with Ctrl+C.
Watch mode only works with local directories, so it cannot be combined with --remote, a positional remote repository URL, --stdout, --stdin, --split-output, --skill-generate, or --copy (whether set on the command line or in your config file).
Examples
# Basic usage
repomix

# Custom output
repomix -o output.xml --style xml

# Output to stdout
repomix --stdout > custom-output.txt

# Send output to stdout, then pipe into another command (for example, simonw/llm)
repomix --stdout | llm "Please explain what this code does."

# Custom output with compression
repomix --compress

# Process specific files
repomix --include "src/**/*.ts" --ignore "**/*.test.ts"

# Split output into multiple files (max size per part)
repomix --split-output 20mb

# Remote repository with branch
repomix --remote https://github.com/user/repo/tree/main

# Remote repository with commit
repomix --remote https://github.com/user/repo/commit/836abcd7335137228ad77feb28655d85712680f1

# Remote repository with shorthand
repomix --remote user/repo

# Watch mode — automatically re-pack on file changes
repomix --watch
repomix -w --include "src/**/*.ts"
Updating Repomix
To update a globally installed Repomix:
# Using npm
npm update -g repomix

# Using yarn
yarn global upgrade repomix

# Using bun
bun update -g repomix
Using npx repomix is generally more convenient as it always uses the latest version.
Remote Repository Processing
Repomix supports processing remote Git repositories without the need for manual cloning. This feature allows you to quickly analyze any public Git repository with a single command.
To process a remote repository, use the --remote option followed by the repository URL:
repomix --remote https://github.com/yamadashy/repomixYou can also use GitHub's shorthand format:
repomix --remote yamadashy/repomixYou can specify the branch name, tag, or commit hash:
# Using --remote-branch option
repomix --remote https://github.com/yamadashy/repomix --remote-branch main

# Using branch's URL
repomix --remote https://github.com/yamadashy/repomix/tree/main
Or use a specific commit hash:
# Using --remote-branch option
repomix --remote https://github.com/yamadashy/repomix --remote-branch 935b695

# Using commit's URL
repomix --remote https://github.com/yamadashy/repomix/commit/836abcd7335137228ad77feb28655d85712680f1
For security, config files (repomix.config.) in remote repositories are not loaded by default. This prevents untrusted repositories from executing code via config files. Your global config and CLI options are still applied. To trust a remote repository's config, use --remote-trust-config or set REPOMIX_REMOTE_TRUST_CONFIG=true — on an interactive terminal Repomix then shows that config and asks you to confirm before loading it. See Remote Repository Config Trust. When using --config with --remote, an absolute path is required (e.g., --config /home/user/repomix.config.json).
Code Compression
The --compress option utilizes Tree-sitter to perform intelligent code extraction, focusing on essential function and class signatures while removing implementation details. This can help reduce token count while retaining important structural information.
repomix --compressFor example, this code:
import { ShoppingItem } from './shopping-item';

/**
 * Calculate the total price of shopping items
 */
const calculateTotal = (
  items: ShoppingItem[]
) => {
  let total = 0;
  for (const item of items) {
    total += item.price * item.quantity;
  }
  return total;
}

// Shopping item interface
interface Item {
  name: string;
  price: number;
  quantity: number;
}
Will be compressed to:
import { ShoppingItem } from './shopping-item';
⋮----
/**
 * Calculate the total price of shopping items
 */
const calculateTotal = (
  items: ShoppingItem[]
) => {
⋮----
// Shopping item interface
interface Item {
  name: string;
  price: number;
  quantity: number;
}
This is an experimental feature that we'll be actively improving based on user feedback and real-world usage
Per-file Inclusion Levels (output.patterns)
While --compress applies one level to every file, output.patterns lets you control the detail level per glob from your config file. Each entry targets files by glob (matched the same way as include/ignore) and overrides the global output.compress setting for matching files:
{
  "output": {
    "compress": false, // global default acts as the catch-all
    "patterns": [
      { "pattern": "docs/**/*", "compress": true },
      { "pattern": "website/**/*", "directoryStructureOnly": true }
    ]
  }
}
There are three levels:
Full content (default) — the file's full content is included.
Compressed (compress: true) — the content is passed through the same Tree-sitter pipeline as --compress.
Directory-structure-only (directoryStructureOnly: true) — the file is listed in the directory structure, but its content block is omitted from the output entirely.
Semantics:
Patterns are evaluated in array order and the first matching pattern wins for a given file.
A matched pattern's flags override the global output.compress setting. A pattern that matches without setting either flag forces full content for that file (useful for whitelisting files out of a global compress).
directoryStructureOnly takes precedence over compress when both are set.
If no pattern matches, the global behavior applies (full content, or compressed when output.compress is true).
This is a config-file-only option; there is no CLI flag for per-pattern levels.
Token Count Optimization
Understanding your codebase's token distribution is crucial for optimizing AI interactions. Use the --token-count-tree option to visualize token usage across your project:
repomix --token-count-treeThis displays a hierarchical view of your codebase with token counts:
🔢 Token Count Tree:
────────────────────
└── src/ (70,925 tokens)
    ├── cli/ (12,714 tokens)
    │   ├── actions/ (7,546 tokens)
    │   └── reporters/ (990 tokens)
    └── core/ (41,600 tokens)
        ├── file/ (10,098 tokens)
        └── output/ (5,808 tokens)
You can also set a minimum token threshold to focus on larger files:
repomix --token-count-tree 1000 # Only show files/directories with 1000+ tokensThis helps you:
Identify token-heavy files that might exceed AI context limits
Optimize file selection using --include and --ignore patterns
Plan compression strategies by targeting the largest contributors
Balance content vs. context when preparing code for AI analysis
Splitting Output for Large Codebases
When working with large codebases, the packed output may exceed file size limits imposed by some AI tools (e.g., Google AI Studio's 1MB limit). Use --split-output to automatically split the output into multiple files:
repomix --split-output 1mbThis generates numbered files like:
repomix-output.1.xml
repomix-output.2.xml
repomix-output.3.xml
Size can be specified with units: 500kb, 1mb, 2mb, 1.5mb, etc. Decimal values are supported.
Files are grouped by top-level directory to maintain context. A single file or directory will never be split across multiple output files.
MCP Server Integration
Repomix supports the Model Context Protocol (MCP), allowing AI assistants to directly interact with your codebase. When run as an MCP server, Repomix provides tools that enable AI assistants to package local or remote repositories for analysis without requiring manual file preparation.
repomix --mcpSandbox Mode
By default the MCP server can read any path the host user can. That is convenient for a trusted local assistant, but too broad when the server is exposed to an untrusted client or agent. The --sandbox flag confines the server's file tools to a single workspace directory:
# Confine to the current working directory
repomix --mcp --sandbox

# Confine to a specific directory
repomix --mcp --sandbox path/to/project
When sandbox mode is on, every path is relative to the workspace root (absolute, ~, .., and Windows drive/UNC paths are refused, as are paths that resolve outside the root through symlinks), config files are not loaded, and only the read-only, root-confined tools are registered; remote packing, skill generation, and attaching external outputs are disabled. The raw file tools (file_system_read_file, file_system_read_directory) are available only in sandbox mode, where the workspace root bounds what they can reach. This is an application-level confinement of the tool surface, not an OS-level sandbox.
Without --sandbox, pack_codebase loads and trusts the repomix.config. in the directory it packs, the same as running repomix there from the command line. A config file is code: it can run when loaded and read files outside the repository. If your assistant may pack directories you don't trust, such as cloned third-party repositories, use --sandbox. See the MCP Server guide for details.
Configuring MCP Servers
To use Repomix as an MCP server with AI assistants like Claude, you need to configure the MCP settings:
For VS Code:
You can install the Repomix MCP server in VS Code using one of these methods:
Using the Install Badge:
[](https://insiders.vscode.dev/redirect/mcp/install?name=repomix&config=%7B%22command%22%3A%22npx%22%2C%22args%22%3A%5B%22-y%22%2C%22repomix%22%2C%22--mcp%22%5D%7D) [](https://insiders.vscode.dev/redirect/mcp/install?name=repomix&config=%7B%22command%22%3A%22npx%22%2C%22args%22%3A%5B%22-y%22%2C%22repomix%22%2C%22--mcp%22%5D%7D&quality=insiders)
Using the Command Line:
code --add-mcp '{"name":"repomix","command":"npx","args":["-y","repomix","--mcp"]}'For VS Code Insiders:
code-insiders --add-mcp '{"name":"repomix","command":"npx","args":["-y","repomix","--mcp"]}'For Cline (VS Code extension):
Edit the cline_mcp_settings.json file:
{
  "mcpServers": {
    "repomix": {
      "command": "npx",
      "args": [
        "-y",
        "repomix",
        "--mcp"
      ]
    }
  }
}
For Cursor:
In Cursor, add a new MCP server from Cursor Settings > MCP > + Add new global MCP server with a configuration similar to Cline.
For Claude Desktop:
Edit the claude_desktop_config.json file with similar configuration to Cline's config.
For Claude Code:
To configure Repomix as an MCP server in Claude Code, use the following command:
claude mcp add repomix -- npx -y repomix --mcpAlternatively, you can use the official Repomix plugins (see Claude Code Plugins section below).
Using Docker instead of npx:
You can use Docker as an alternative to npx for running Repomix as an MCP server:
{
  "mcpServers": {
    "repomix-docker": {
      "command": "docker",
      "args": [
        "run",
        "-i",
        "--rm",
        "ghcr.io/yamadashy/repomix",
        "--mcp"
      ]
    }
  }
}
Once configured, your AI assistant can directly use Repomix's capabilities to analyze codebases without manual file preparation, making code analysis workflows more efficient.
Available MCP Tools
When running as an MCP server, Repomix provides the following tools:
pack_codebase: Package a local code directory into a consolidated XML file for AI analysis
Parameters:
directory: Absolute path to the directory to pack
compress: (Optional, default: false) Enable Tree-sitter compression to extract essential code signatures and structure while removing implementation details. Reduces token usage by ~70% while preserving semantic meaning. Generally not needed since grep_repomix_output allows incremental content retrieval. Use only when you specifically need the entire codebase content for large repositories.
includePatterns: (Optional) Specify files to include using fast-glob patterns. Multiple patterns can be comma-separated (e.g., "/.{js,ts}", "src/,docs/"). Only matching files will be processed.
ignorePatterns: (Optional) Specify additional files to exclude using fast-glob patterns. Multiple patterns can be comma-separated (e.g., "test/,.spec.js", "node_modules/,dist/"). These patterns supplement .gitignore, .ignore, and built-in exclusions.
outputPatterns: (Optional) Per-file inclusion levels, mirroring the config-file output.patterns option. An array of { pattern, compress?, directoryStructureOnly? } entries; the first matching pattern wins, directoryStructureOnly takes precedence over compress, and a match with neither flag forces full content (useful for exempting files from a global compress). Overrides any output.patterns from the target repository's repomix.config.json.
topFilesLength: (Optional, default: 10) Number of largest files by size to display in the metrics summary for codebase analysis.
attach_packed_output: Attach an existing Repomix packed output file for AI analysis
Parameters:
path: Path to a directory containing repomix-output.xml or direct path to a packed repository XML file
topFilesLength: (Optional, default: 10) Number of largest files by size to display in the metrics summary
Features:
Accepts either a directory containing a repomix-output.xml file or a direct path to an XML file
Registers the file with the MCP server and returns the same structure as the pack_codebase tool
Provides access to existing packed outputs without requiring re-processing
Useful for working with previously generated packed repositories
pack_remote_repository: Fetch, clone, and package a GitHub repository into a consolidated XML file for AI analysis
Parameters:
remote: GitHub repository URL or user/repo format (e.g., "yamadashy/repomix", "https://github.com/user/repo", or "https://github.com/user/repo/tree/branch")
compress: (Optional, default: false) Enable Tree-sitter compression to extract essential code signatures and structure while removing implementation details. Reduces token usage by ~70% while preserving semantic meaning. Generally not needed since grep_repomix_output allows incremental content retrieval. Use only when you specifically need the entire codebase content for large repositories.
includePatterns: (Optional) Specify files to include using fast-glob patterns. Multiple patterns can be comma-separated (e.g., "/.{js,ts}", "src/,docs/"). Only matching files will be processed.
ignorePatterns: (Optional) Specify additional files to exclude using fast-glob patterns. Multiple patterns can be comma-separated (e.g., "test/,.spec.js", "node_modules/,dist/"). These patterns supplement .gitignore, .ignore, and built-in exclusions.
outputPatterns: (Optional) Per-file inclusion levels, mirroring the config-file output.patterns option. An array of { pattern, compress?, directoryStructureOnly? } entries; the first matching pattern wins, directoryStructureOnly takes precedence over compress, and a match with neither flag forces full content (useful for exempting files from a global compress).
topFilesLength: (Optional, default: 10) Number of largest files by size to display in the metrics summary for codebase analysis.
read_repomix_output: Read the contents of a Repomix-generated output file. Supports partial reading with line range specification for large files.
Parameters:
outputId: ID of the Repomix output file to read
startLine: (Optional) Starting line number (1-based, inclusive). If not specified, reads from beginning.
endLine: (Optional) Ending line number (1-based, inclusive). If not specified, reads to end.
Features:
Specifically designed for web-based environments or sandboxed applications
Retrieves the content of previously generated outputs using their ID
Provides access to packed codebase without requiring file system access
Supports partial reading for large files
grep_repomix_output: Search for patterns in a Repomix output file using grep-like functionality with JavaScript RegExp syntax
Parameters:
outputId: ID of the Repomix output file to search
pattern: Search pattern (JavaScript RegExp regular expression syntax)
contextLines: (Optional, default: 0) Number of context lines to show before and after each match. Overridden by beforeLines/afterLines if specified.
beforeLines: (Optional) Number of context lines to show before each match (like grep -B). Takes precedence over contextLines.
afterLines: (Optional) Number of context lines to show after each match (like grep -A). Takes precedence over contextLines.
ignoreCase: (Optional, default: false) Perform case-insensitive matching
Features:
Uses JavaScript RegExp syntax for powerful pattern matching
Supports context lines for better understanding of matches
Allows separate control of before/after context lines
Case-sensitive and case-insensitive search options
file_system_read_file: Read a file inside the sandbox workspace. Only available in sandbox mode (--sandbox), where the workspace root bounds what it can reach.
Parameters:
path: Path to the file to read, relative to the workspace root (e.g. src/index.ts)
Notes:
Not registered without --sandbox
Content matching known secret formats (Secretlint) is refused as an additional heuristic safeguard — the access boundary is the workspace root, not the scan
file_system_read_directory: List the contents of a directory inside the sandbox workspace. Only available in sandbox mode (--sandbox).
Parameters:
path: Path to the directory to list, relative to the workspace root (e.g. . or src)
Features:
Shows files and directories with clear indicators ([FILE] or [DIR])
Useful for exploring project structure and understanding codebase organization
Claude Code Plugins
Repomix provides official plugins for Claude Code that integrate seamlessly with the AI-powered development environment.
Installation
1. Add the Repomix plugin marketplace:
/plugin marketplace add yamadashy/repomix2. Install plugins:
# Install MCP server plugin (recommended foundation)
/plugin install repomix-mcp@repomix

# Install commands plugin (extends functionality)
/plugin install repomix-commands@repomix

# Install repository explorer plugin (AI-powered analysis)
/plugin install repomix-explorer@repomix
Note: The repomix-mcp plugin is recommended as a foundation. The repomix-commands plugin provides convenient slash commands, while repomix-explorer adds AI-powered analysis capabilities. While you can install them independently, using all three provides the most comprehensive experience.
Alternatively, use the interactive plugin installer:
/pluginThis will open an interactive interface where you can browse and install available plugins.
Available Plugins
1. repomix-mcp (MCP Server Plugin)
Foundation plugin that provides AI-powered codebase analysis through MCP server integration.
Features:
Pack local and remote repositories
Read and search packed outputs
Automatic Tree-sitter compression (~70% token reduction)
2. repomix-commands (Slash Commands Plugin)
Provides convenient slash commands for quick operations with natural language support.
Available Commands:
/repomix-commands:pack-local - Pack local codebase with various options
/repomix-commands:pack-remote - Pack and analyze remote GitHub repositories
Example usage:
/repomix-commands:pack-local
Pack this project as markdown with compression

/repomix-commands:pack-remote yamadashy/repomix
Pack only TypeScript files from the yamadashy/repomix repository
3. repomix-explorer (AI Analysis Agent Plugin)
AI-powered repository analysis agent that intelligently explores codebases using Repomix CLI.
Features:
Natural language codebase exploration and analysis
Intelligent pattern discovery and code structure understanding
Incremental analysis using grep and targeted file reading
Automatic context management for large repositories
Available Commands:
/repomix-explorer:explore-local - Analyze local codebase with AI assistance
/repomix-explorer:explore-remote - Analyze remote GitHub repositories with AI assistance
Example usage:
/repomix-explorer:explore-local ./src
Find all authentication-related code

/repomix-explorer:explore-remote facebook/react
Show me the main component architecture
The agent automatically:
Runs npx repomix@latest to pack the repository
Uses Grep and Read tools to efficiently search the output
Provides comprehensive analysis without consuming excessive context
Benefits
Seamless Integration: Claude can directly analyze codebases without manual preparation
Natural Language: Use conversational commands instead of remembering CLI syntax
Always Latest: Automatically uses npx repomix@latest for up-to-date features
Secret Scanning: Secretlint flags files matching known credential formats so they are left out of the output
Token Optimization: Tree-sitter compression for large codebases
For more details, see the plugin documentation in the .claude/plugins/ directory.
Agent Skills Generation
Repomix can generate Claude Agent Skills format output, creating a structured Skills directory that can be used as a reusable codebase reference for AI assistants. This feature is particularly powerful when you want to reference implementations from remote repositories.
Basic Usage
# Generate Skills from local directory
repomix --skill-generate

# Generate with custom Skills name
repomix --skill-generate my-project-reference

# Generate with a custom project name in Skills descriptions
repomix --skill-generate --skill-project-name "My Project"

# Generate from remote repository
repomix --remote https://github.com/user/repo --skill-generate
When you run the command, Repomix prompts you to choose where to save the Skills:
Personal Skills (~/.claude/skills/) - Available across all projects on your machine
Project Skills (.claude/skills/) - Shared with your team via git
Non-Interactive Usage
For CI pipelines and automation scripts, you can skip all interactive prompts using --skill-output and --force:
# Specify output directory directly
repomix --skill-generate --skill-output ./my-skills

# Skip overwrite confirmation with --force
repomix --skill-generate --skill-output ./my-skills --force

# Full non-interactive example
repomix --remote user/repo --skill-generate my-skill --skill-output ./output --force
Generated Structure
The Skills are generated with the following structure:
.claude/skills/<skill-name>/
├── SKILL.md                 # Main Skills metadata & documentation
└── references/
    ├── summary.md           # Purpose, format, and statistics
    ├── project-structure.md # Directory tree with line counts
    ├── files.md             # All file contents (grep-friendly)
    └── tech-stacks.md       # Languages, frameworks, dependencies
What's Included
SKILL.md: Contains Skills metadata, file/line/token counts, overview, and usage instructions
summary.md: Explains the Skills' purpose, usage guidelines, and provides statistics breakdown by file type and language
project-structure.md: Directory tree with line counts per file for easy file discovery
files.md: All file contents with syntax highlighting headers, optimized for grep-friendly searching
tech-stacks.md: Auto-detected tech stack per package from dependency files (package.json, requirements.txt, Cargo.toml, etc.)
Auto-Generated Skills Names
If no name is provided, Repomix auto-generates one:
repomix src/ --skill-generate                # → repomix-reference-src
repomix --remote user/repo --skill-generate  # → repomix-reference-repo
repomix --skill-generate CustomName          # → custom-name (normalized to kebab-case)
Integration with Repomix Features
Skills generation respects all standard Repomix options:
# Generate Skills with file filtering
repomix --skill-generate --include "src/**/*.ts" --ignore "**/*.test.ts"

# Generate Skills with compression
repomix --skill-generate --compress

# Generate Skills from remote repository
repomix --remote yamadashy/repomix --skill-generate
Repomix Explorer Skill (Agent Skills)
Repomix provides a ready-to-use Repomix Explorer skill that enables AI coding assistants to analyze and explore codebases using Repomix CLI. This skill is designed to work with various AI tools including Claude Code, Cursor, Codex, GitHub Copilot, and more.
Quick Install
For Claude Code, install the official Repomix Explorer plugin:
/plugin marketplace add yamadashy/repomix
/plugin install repomix-explorer@repomix
For Codex, Cursor, OpenClaw, and other Agent Skills-compatible assistants, install the standalone skill with the Skills CLI:
npx skills add yamadashy/repomix --skill repomix-explorerTo target a specific assistant, pass --agent:
npx skills add yamadashy/repomix --skill repomix-explorer --agent codex
npx skills add yamadashy/repomix --skill repomix-explorer --agent openclaw
For Hermes Agent, install the single-file skill with Hermes Agent's native skills command:
hermes skills install https://raw.githubusercontent.com/yamadashy/repomix/main/skills/repomix-explorer/SKILL.mdWhat It Does
Once installed, you can analyze codebases with natural language instructions.
Analyze remote repositories:
"What's the structure of this repo?
https://github.com/facebook/react"
Explore local codebases:
"What's in this project?
~/projects/my-app"
This is useful not only for understanding codebases, but also when you want to implement features by referencing your other repositories.
⚙️ Configuration
Repomix supports multiple configuration file formats for flexibility and ease of use.
Configuration File Formats
Repomix will automatically search for configuration files in the following priority order:
TypeScript (repomix.config.ts, repomix.config.mts, repomix.config.cts)
JavaScript/ES Module (repomix.config.js, repomix.config.mjs, repomix.config.cjs)
JSON (repomix.config.json5, repomix.config.jsonc, repomix.config.json)
JSON Configuration
Create a repomix.config.json file in your project root:
repomix --initThis will create a repomix.config.json file with default settings.
TypeScript Configuration
TypeScript configuration files provide the best developer experience with full type checking and IDE support.
Installation:
To use TypeScript or JavaScript configuration with defineConfig, you need to install Repomix as a dev dependency:
npm install -D repomixExample:
// repomix.config.ts
import { defineConfig } from 'repomix';

export default defineConfig({
  output: {
    filePath: 'output.xml',
    style: 'xml',
    removeComments: true,
  },
  ignore: {
    customPatterns: ['**/node_modules/**', '**/dist/**'],
  },
});
Benefits:
✅ Full TypeScript type checking in your IDE
✅ Excellent IDE autocomplete and IntelliSense
✅ Use dynamic values (timestamps, environment variables, etc.)
Dynamic Values Example:
// repomix.config.ts
import { defineConfig } from 'repomix';

// Generate timestamp-based filename
const timestamp = new Date().toISOString().slice(0, 19).replace(/[:.]/g, '-');

export default defineConfig({
  output: {
    filePath: `output-${timestamp}.xml`,
    style: 'xml',
  },
});
JavaScript Configuration
JavaScript configuration files work the same as TypeScript, supporting defineConfig and dynamic values.
This is an excerpt of a longer README. Open the source for the complete document.
Read the original README